Tuning for Throughput vs. Durability — acks, Batching, Compression & Common Pitfalls
Today's Requirement
Marketing tells you a flash sale goes live next week. Clickstream volume will jump from a trickle to tens of thousands of events per second, for hours.
Every producer setting you have used so far worked fine for 20 test messages. At flash-sale volume, the same defaults could cost real money, or become a real bottleneck.
The question is: are your producers ready?
To answer it, you need to know the settings that control the trade-off between speed and safety. Today we look at five of them. And instead of only reading about them, you will measure their effect yourself.
The Five Knobs
| Knob | What it controls |
|---|---|
linger.ms | How long messages wait in the buffer to form a batch |
batch.size and batch.num.messages | How big one batch may grow |
compression.type | Whether batches are compressed before they go over the network |
acks | How much confirmation the producer waits for |
How often you poll() | How quickly delivery reports are handled |
Let's take them one at a time.
Knob 1: linger.ms — Trading a Little Latency for a Lot of Throughput
Remember what you learned about producer internals. produce() does not send a message at once. The message waits in an internal buffer, and a background thread sends messages in batches.
How long does a message wait?
That is exactly what linger.ms controls. Its default is 5 milliseconds.
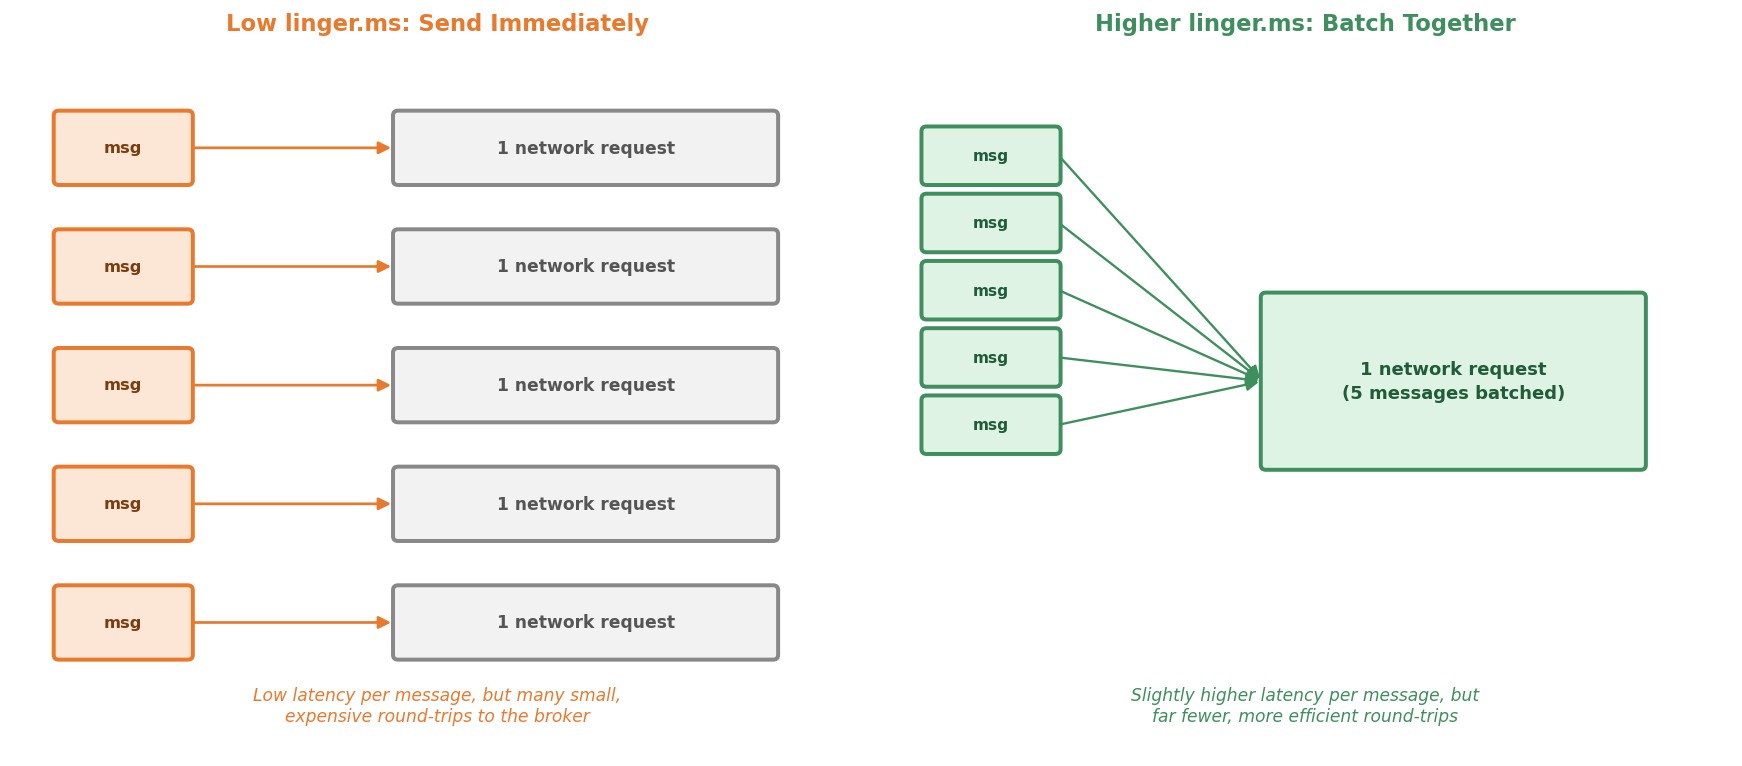 Low vs. high linger.ms
- With a low
linger.ms, messages leave almost at once. Each message has low latency. But you get many small batches, so many more network round trips. - With a higher
linger.ms, the producer waits a little longer, and more messages pile up. Then it sends them as one bigger batch. Each message waits a little longer. But you get far fewer, far more efficient round trips.
Think of two numbers. In 5 ms, you may collect 50 events. In 50 ms, you may collect 2,000. Ten times the waiting time, but many times the batch size.
Can I make it very large, like one minute?
No. Think about it. Every message would wait up to a minute. That is bad for latency. And if you produce very fast, a very high value lets messages pile up in the buffer. The buffer has limits (see Knob 5). When they are reached, produce() fails. So choose a moderate value, and test it.
Knob 2: batch.size and batch.num.messages — How Big a Batch May Get
Two more settings put an upper limit on one batch:
| Setting | Default | What it limits |
|---|---|---|
batch.size | 1,000,000 bytes (about 1 MB) | The total size of the batch |
batch.num.messages | 10,000 | The number of messages in the batch |
A batch is sent when the first of three things happens: linger.ms has passed, the size limit is reached, or the message limit is reached.
Which limit do we usually hit?
Kafka events are small, often much less than 1 KB. So 10,000 events are only a few megabytes at most, and usually much less. That means for small events, the message limit (10,000) is the one you reach first, not the size limit.
Let's do a small example. Suppose linger.ms is 300 ms, and in those 300 ms your loop collects 50,000 events. A batch is limited to 10,000 messages. So the producer sends five batches, and not one.
Should you change these?
Usually not. 10,000 messages and 1 MB are decent limits. If your events are tiny, you can raise the message count. But sending very large packets is a different kind of problem, so do not go far beyond about 1 MB unless you have a specific reason.
Knob 3: compression.type — Batching's Natural Partner
compression.type shrinks a batch before it goes over the network. The options are none (the default), gzip, snappy, lz4 and zstd.
This is not a separate decision from batching. It is the same decision, and the two help each other. Compression works on a whole batch at once. So the bigger your batches, the better the compression works. A higher linger.ms and a real compression codec are usually turned on together.
The price is CPU time. Compressing (and later decompressing) costs processing.
lz4andsnappyare fast. They are the common choice for high-throughput pipelines.gzipcompresses smaller, but it costs more CPU. It is a poor fit if low latency matters more than saving bytes.zstdis another good option with strong compression.
Why is the default none?
Because if your batches hold only a few small messages, compression saves almost nothing and only costs CPU. Compression pays off when batches are bigger.
Knob 4: acks — How Much Durability You Wait For
You already used acks in the last lecture. Now let's look at all three levels together.
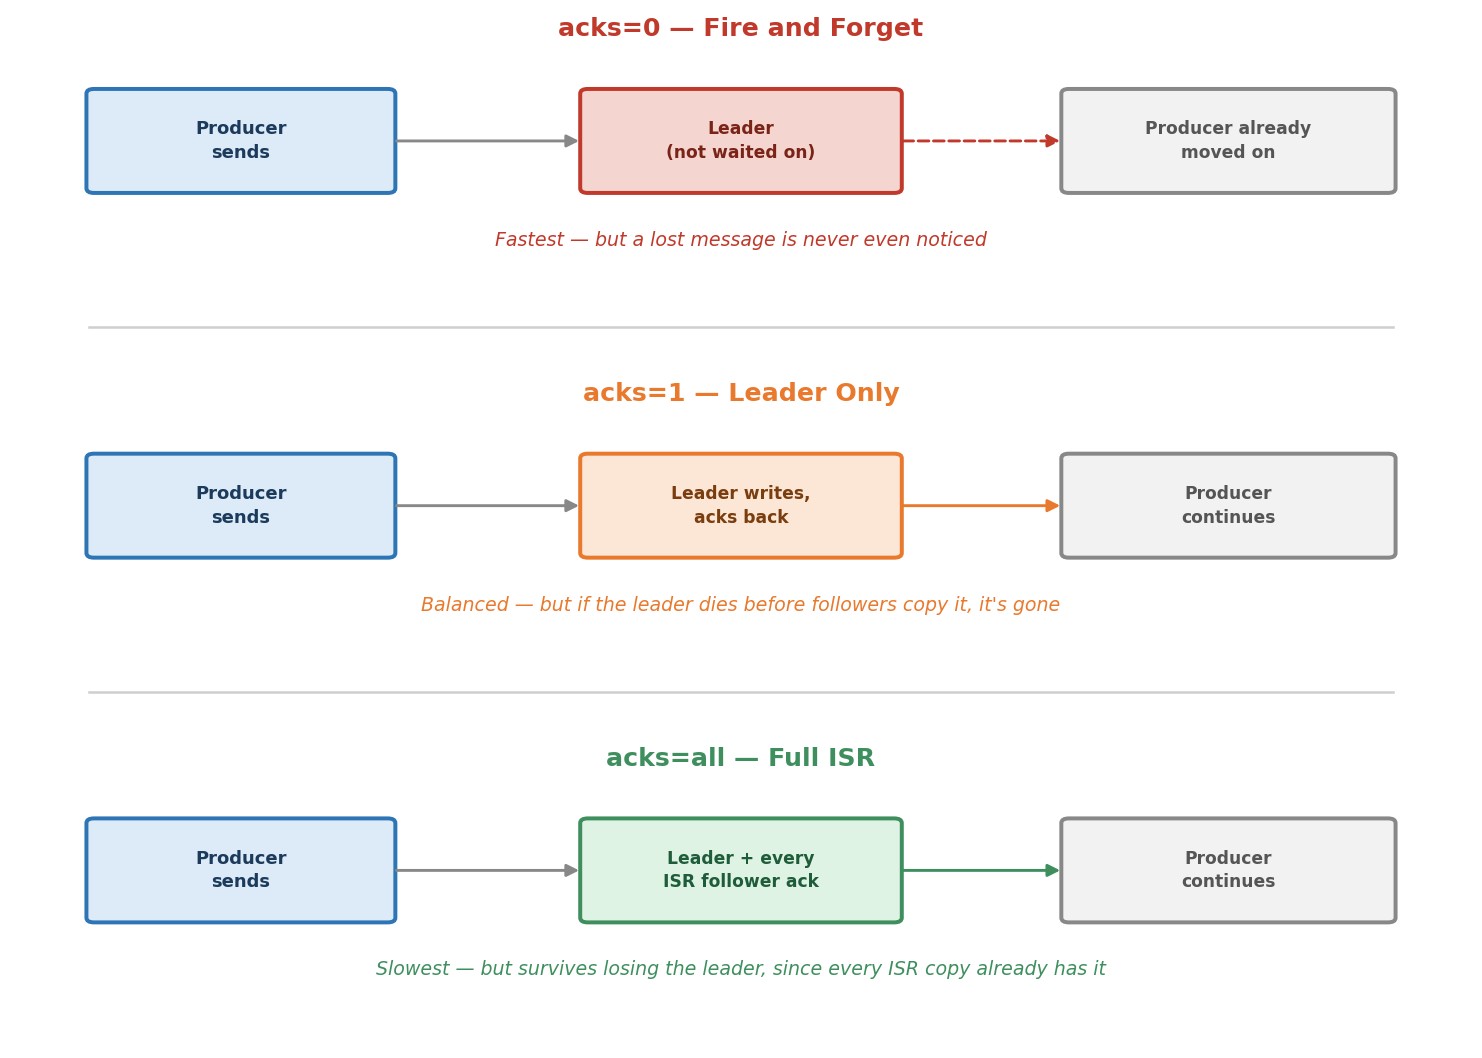 Three acks levels
acks=0 waits for nothing. The producer sends and moves on. It is the fastest and the riskiest. If a message never reaches the broker, your code has no way to know. Use it only for data you can afford to lose.
acks=1 waits for the partition leader to write the message and confirm. It is quick and reasonably safe. But there is a real gap. If the leader fails before the followers copied the message, the message is gone, even though the producer was told it succeeded.
acks=all waits for every replica that is currently in sync (the ISR) to confirm. It is the slowest of the three. But it survives losing the leader, because every in-sync copy already has the message.
Output / NoteWhich one is the default? In
confluent-kafka, the default isacks=all. In the videos, the default was described as 1. It isall. The benchmark script below setsacksto 1 explicitly, on purpose, to represent the faster setting.
Is acks=all always a full guarantee?
Only if the ISR really contains more than the leader. If followers fall out of sync, "all in-sync replicas" can shrink to just the leader. Then acks=all is no better than acks=1. The broker setting min.insync.replicas protects you from this. For example, with min.insync.replicas=2, a write is refused when fewer than two replicas are in sync. For data you cannot lose, use acks=all together with min.insync.replicas of 2 or more.
Knob 5: How Often You poll()
After every produce(), so far, we called poll(0). Is that the best choice?
Remember what poll() does: it hands the delivery reports (the answers) to your callbacks. Two things are true at the same time:
- You must poll regularly. If you do not, delivery reports pile up in memory, waiting for you. Unserved reports count against the producer's internal queue, which has limits.
- Polling after every single message is often more than you need. A
poll(0)is cheap, but it is not free. At tens of thousands of messages per second, you can call it every few hundred or thousand messages instead. Our benchmark script does exactly that: it polls once every 1,000 messages.
The balance depends on linger.ms. With a very small value, answers come back quickly and often, so poll more often. With a larger value, answers come back in bursts.
What happens if the internal queue fills up?
The producer's queue holds at most 100,000 messages or about 1 GB by default (queue.buffering.max.messages and queue.buffering.max.kbytes). When it is full, produce() raises a BufferError with the text Local: Queue full. It does not crash the program by magic. Your code must handle it. The usual way is: give the producer time to catch up with poll(), then try again.
pythontry: producer.produce(topic=TOPIC, key=key, value=value) except BufferError: producer.poll(1) # give the client time to send and to serve callbacks producer.produce(topic=TOPIC, key=key, value=value)
(This is an example. It is not part of the benchmark script.)
Let's Measure It, Not Just Reason About It
Now let's see the effect on your own cluster.
The Benchmark Script
The script has one producer, and three sets of settings. You choose the set with a command-line argument:
pythonTOPIC = "clickstream-benchmark" NUM_MESSAGES = 20000 CONFIGS = { "baseline": { "acks": 1, "linger.ms": 5, "batch.size": 1000000, "compression.type": "none", }, "throughput": { "acks": 1, "linger.ms": 50, "batch.size": 1000000, "compression.type": "lz4", }, "durability": { "acks": "all", "linger.ms": 5, "batch.size": 1000000, "compression.type": "lz4", }, }
Let's read the three scenarios:
baseline: the plain settings.linger.ms(5),batch.sizeandcompression.typeare the defaults.acksis set to 1, which is not the default (the comment in the file calls the whole set "librdkafka's own defaults", butacksis the exception).throughput: built for speed. It waits 50 ms to make bigger batches, and compresses them withlz4.durability: built for safety.acks=all, and it also useslz4.
The script sends 20,000 events, and measures the time:
pythonstart = time.time() for i in range(NUM_MESSAGES): event = { "user_id": f"user-{i % 500}", "event_type": "page_view", "event_time": time.time(), } producer.produce( topic=TOPIC, key=str(i % 500).encode("utf-8"), value=json.dumps(event).encode("utf-8"), ) if i % 1000 == 0: producer.poll(0) producer.flush() elapsed = time.time() - start throughput = NUM_MESSAGES / elapsed
Notice the differences from earlier producers. There is no sleep, so the loop runs as fast as it can. There is no callback (to keep things simple and fast). And it polls only every 1,000 messages.
Step 1: Start Your Cluster
bashdocker compose start docker ps
Step 2: Create a Dedicated Benchmark Topic
bashdocker exec -it kafka-1 bash export PATH=$PATH:/opt/kafka/bin
bashkafka-topics.sh --create \ --topic clickstream-benchmark \ --bootstrap-server kafka-1:29092 \ --partitions 3 \ --replication-factor 3
Step 3: Run All Three Scenarios
In your 01_producers folder, on the host machine, one after the other:
bashpython 5-throughput_benchmark.py baseline python 5-throughput_benchmark.py throughput python 5-throughput_benchmark.py durability
(If you make a mistake in the argument, the script prints a usage line. That line shows python3 and the file name without the 5- prefix. Use python and the real file name.)
Each run prints how long it took and how many messages per second. Write down all three numbers.
Step 4: Read Your Results Honestly
In the recorded run, the three numbers were about 0.16 s for baseline, 0.12 s for throughput, and 0.14 s for durability. Your numbers will be different.
Please read them with care.
- This is a small cluster on your own laptop, not production hardware on a real network. The absolute numbers mean nothing in the real world. Replication between containers on one machine is almost free, so the cost of
acks=alllooks much smaller than it would in production. - 20,000 messages finish in a fraction of a second. At that size, timing noise is as big as the differences between scenarios. Run each scenario three times and compare. The order can change from one run to the next.
- The scenarios differ in more than one setting.
durabilitydiffers frombaselineinacksand in compression. So a fastdurabilityresult does not prove thatacks=allis fast. To measure one knob alone, change only that one in the dictionary and run again.
Want a clearer signal? Raise NUM_MESSAGES at the top of the file, for example to 200,000, and run again. With very large numbers on a slow machine, you may meet the BufferError from Knob 5. The script does not handle it. If that happens, you have just seen the queue limit in action.
What matters is the method: change one thing, measure, compare. Do not tune by guessing.
Step 5: Stop Your Cluster
bashdocker compose stop
Common Producer Pitfalls in Production
These mistakes show up constantly in real systems.
Using acks=0 for anything that matters. It is fast, but silent data loss is not a possibility. Sooner or later it is a certainty. Keep it for data you can afford to lose.
Believing acks=1 is the default. The default is all. If you see acks=1 in a config, someone chose it.
Never checking the delivery callback. produce() not raising an error tells you nothing about delivery. Errors arrive in the callback, later. Code that ignores err can run for months while hiding real message loss.
Not calling poll() often enough. Delivery reports pile up, the internal queue fills, and produce() starts raising BufferError. Handle it: poll, then retry.
Forgetting flush() before the program exits. Messages still in the buffer are lost.
Using gzip in a latency-sensitive pipeline. It compresses well, but it is the slowest common codec. For most high-throughput pipelines, lz4 or snappy is a better default.
Trusting acks=all without min.insync.replicas. If the ISR shrinks to the leader, acks=all is only as safe as acks=1.
Tuning blindly. Guessing at linger.ms or batch.size instead of measuring them on your own workload and cluster.
Checklist
- Understood how
linger.mstrades a little latency for far fewer network round trips - Know that a batch is sent when
linger.ms,batch.sizeorbatch.num.messagesis reached first, and which one small events usually hit - Understood why compression works best with big batches, and what it costs in CPU
- Understood what each
ackslevel waits for and what it risks, and that the default isall - Know why
min.insync.replicasmatters foracks=all - Understood why you must poll regularly, why not after every message at high rates, and what
BufferErrormeans - Ran all three benchmark scenarios, and read the numbers with their limits in mind
- Know the common producer pitfalls, and why each one causes real incidents
You have tuned a real producer for a real trade-off, with real measurements to back the decision, and not just a rule of thumb. That completes the producer side. Next, we look at the other side of Kafka: reading the data with consumers.