Capstone: ShopStream
Part 2: Design and approach
Before you write code, think
On your first day, do not open the editor first.
Take a plain sheet of paper. Write down three questions:
- What happens to an event from the moment it is created until it is saved?
- What can go wrong on the way?
- For each problem, which Kafka feature fixes it?
This part answers those questions for ShopStream. You will see the design, and why each choice was made. There is no solution code here. The code comes in Part 3.
Read this part fully before you start building. If you get stuck later, come back to the matching section.
1. The big picture
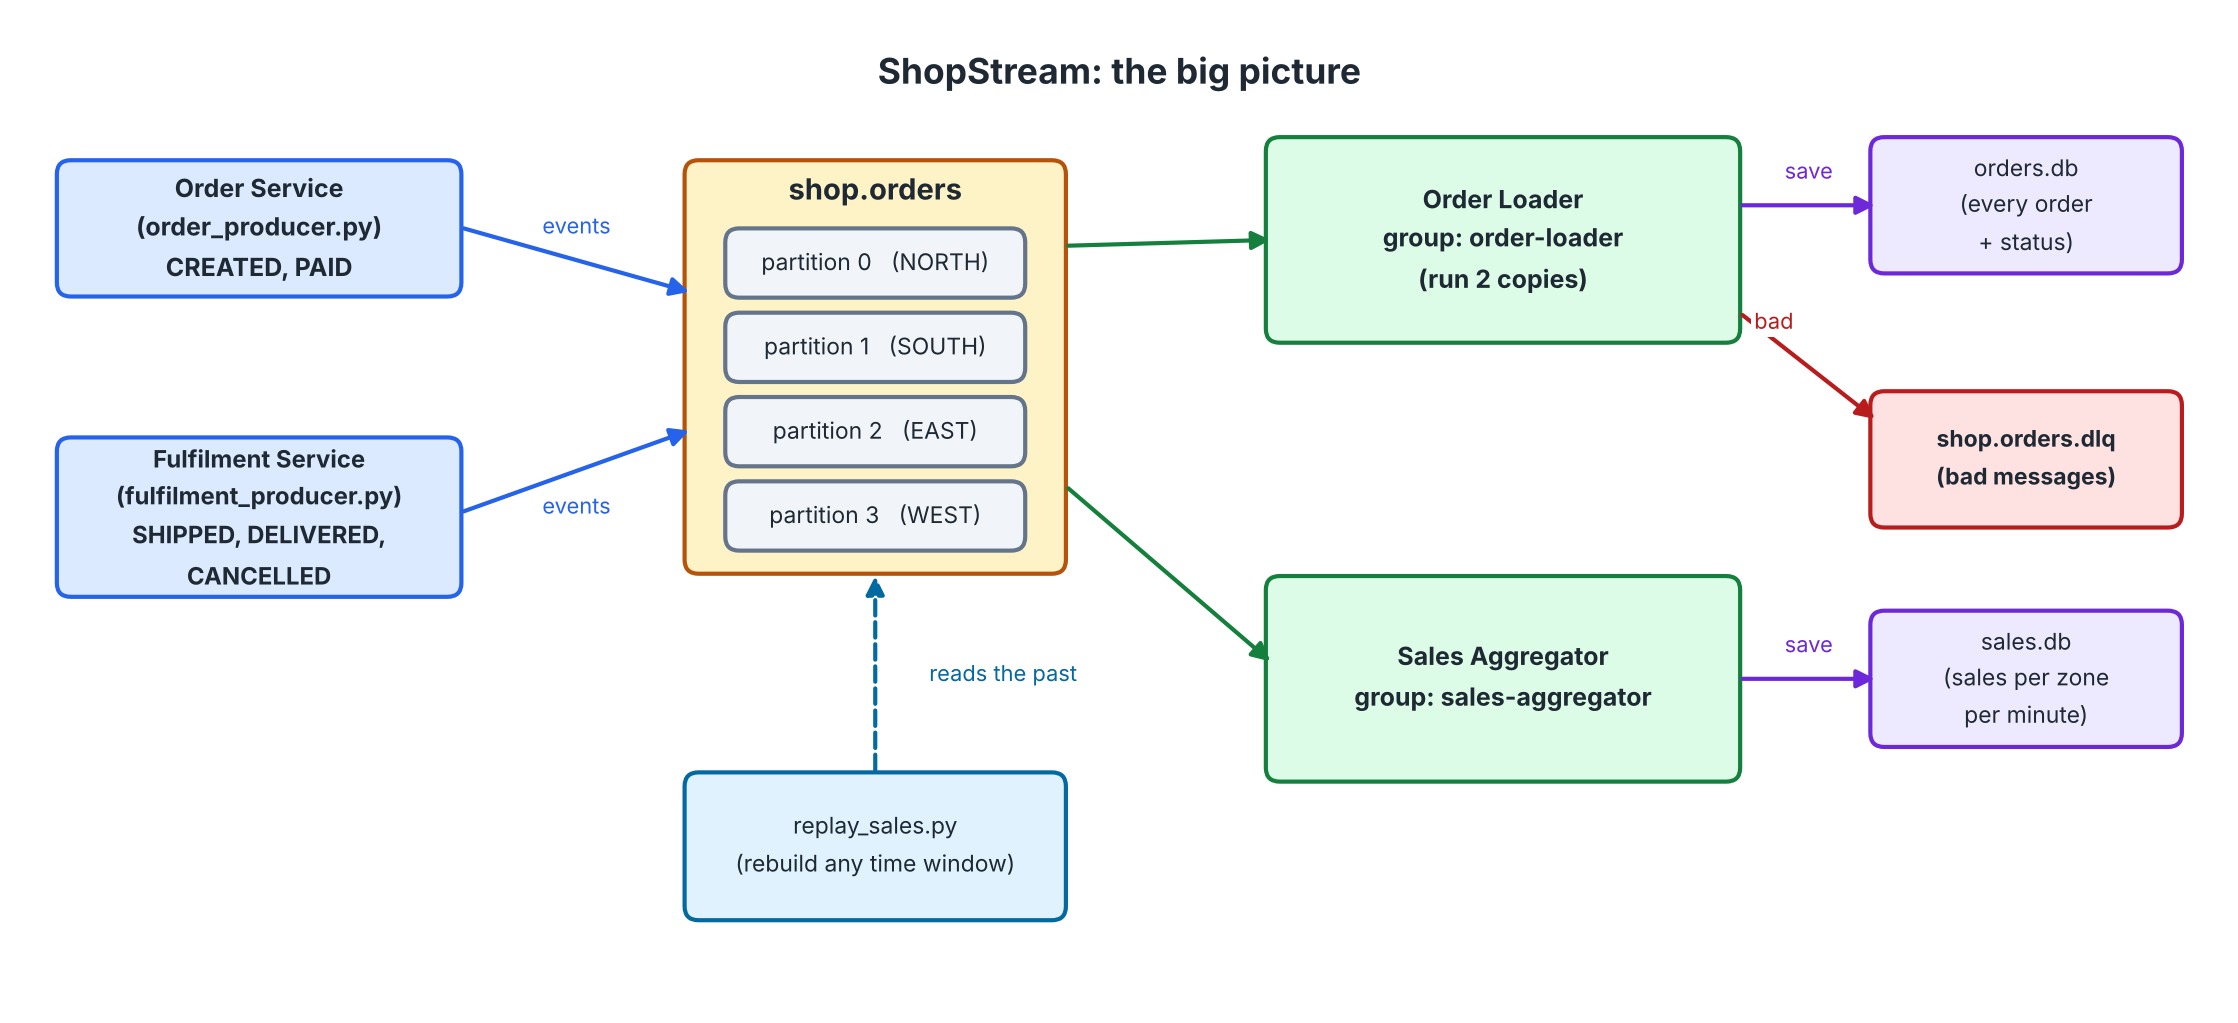 The big picture
Read the picture from left to right.
- Two services send events into one topic,
shop.orders. - Two consumer groups read the topic. They do not know about each other.
- The Order Loader saves orders in
orders.db. Bad messages go to the dead-letter topic. - The Sales Aggregator saves sales per zone, per minute in
sales.db. - The Replay tool can read the past from the topic at any time.
Why one topic and not many? All of these events are about orders. One topic keeps them together. Each consumer group picks what it needs.
Why two consumer groups? The loader and the aggregator do different jobs. Each must see every event. Two groups give each of them its own copy of the stream — exactly the rule from the consumer chapter: different group.id, independent position, both read everything.
2. The topics
| Topic | Partitions | Replication | min.insync.replicas |
|---|---|---|---|
shop.orders | 4 | 3 | 2 |
shop.orders.dlq | 3 | 3 | 2 |
Why 4 partitions? We have four zones. One partition for each zone is a simple rule to explain. It also lets up to four consumers share the work.
Why replication 3 and min.insync.replicas 2? Every message is stored on three brokers. A write is accepted only when at least two have it. So we can lose one broker and keep working, and we never accept a write that lives on only one broker.
Why a separate dead-letter topic? A bad message must not stop the pipeline. It must also not disappear. The dead-letter topic is a safe parking place. Someone can look at it later.
3. Keys and partitions
The key
The key is order_id.
Why? Kafka keeps the order of messages inside one partition. If all events of one order have the same key, they go to the same partition. They are then read in the order they were written.
Our own partition rule — as a real Partitioner
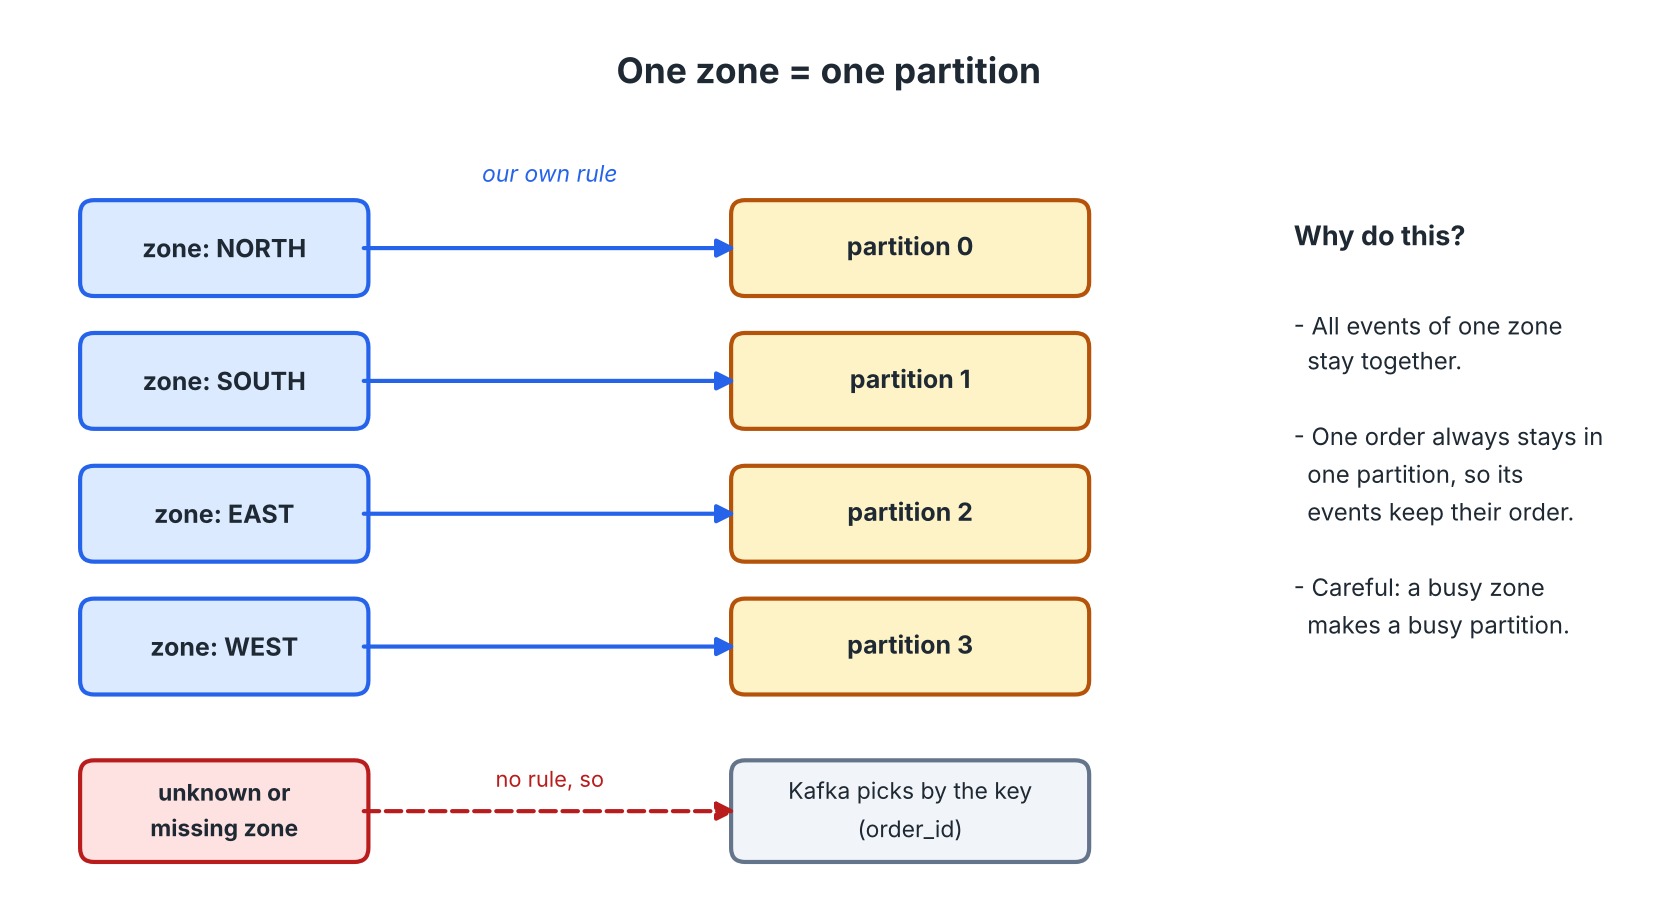 One zone, one partition
We do not leave the choice to Kafka's key rule. We say: one zone, one partition. And unlike a Python producer, where the simplest way to do this is to compute a partition number by hand and attach it to the message, the Java producer gives you a proper extension point for exactly this: the Partitioner interface, the same one PremiumPartitioner used in the producer chapter.
So ZonePartitioner is a small class — configure(), partition(), close() — registered on the producer with partitioner.class. It is never called directly by your sending code. The producer calls it for every record, right before the record leaves for the network.
Why read the zone from the message, and not rely on the key?
Because the zone is what the business rule is actually about. Reading it straight from the record's own JSON means the rule stays correct even for a status event that has not picked up a key yet, and it keeps the partitioning decision entirely inside the partitioner — your sending code does not need to know the rule exists.
What is the cost? A zone with more orders makes a busier partition. In our data, SOUTH is busier than EAST. With the default key rule, load would be more even. We choose the simple rule on purpose, and we know the cost. This is a real design trade-off.
What about a bad zone? If the zone is missing or unknown, our rule has no answer. We do not invent one. We fall back to exactly what the default partitioner would have done if we had never registered ZonePartitioner at all: hash the key with the same Murmur2 algorithm Kafka itself uses — the one this course verified independently, by hand, in the producer chapter — or spread null-key messages round-robin if there is no key either. The Order Loader will move the message to the dead-letter topic later; the partitioner's job is only to make a reasonable choice, not a correct one.
Where does the rule live? In its own class, with no database code and no consumer code inside. Both producers register it through partitioner.class; neither one calls it by name. Because the zone-reading logic is a small static method, you can test it directly, with no Cluster object and no running broker.
4. The producers
Two services, shared code
The Order Service and the Fulfilment Service do the same kind of work. They read a file and send lines to Kafka. Only the file and the client.id are different.
So write the sending code once, in a shared class, OrderFeed. Each service becomes a very short class that calls it.
Settings and why
| Setting | Value | Why |
|---|---|---|
enable.idempotence | true | A retry must never create a duplicate or change the order |
acks | all | Wait until all in-sync replicas have the message |
linger.ms | 50 | Wait a little so messages travel in groups |
batch.size | 65536 | The size of one group |
compression.type | lz4 | Smaller messages, less network |
partitioner.class | ZonePartitioner | Our own zone rule |
client.id | the service name | Easy to find in logs |
What the sending loop must handle
- A good JSON event: add
event_timeif it is missing, useorder_idas the key. (The partition is not decided here —ZonePartitionerdecides it, automatically, the moment the record is handed tosend().) - A line that is not a JSON object: send it as it is. No key.
- The end:
flush()waits for the last messages. Then the program prints its counts and sets its exit code.
What about a full local buffer? This is the one place a Java producer behaves differently from the librdkafka-based clients this course's Python track would use. There, produce() returns immediately and raises an error the moment the local queue is full, so your own code has to catch that error, wait, and retry by hand. The Java producer's send() does that waiting for you, internally, up to max.block.ms (60 seconds by default — you met this in the producer-tuning lecture). So there is no retry loop to write. There is still something to handle: if the buffer is still full after that whole wait, send() throws a TimeoutException, and your code needs to catch it the same way it catches a delivery failure in the callback — count it, report it, and make sure the exit code reflects it.
Why does the producer forward broken lines? Think about a real company. The producer may be a gateway that must never lose data. It does not judge. The consumer checks the data, because the consumer knows what the business needs.
5. Consumer groups
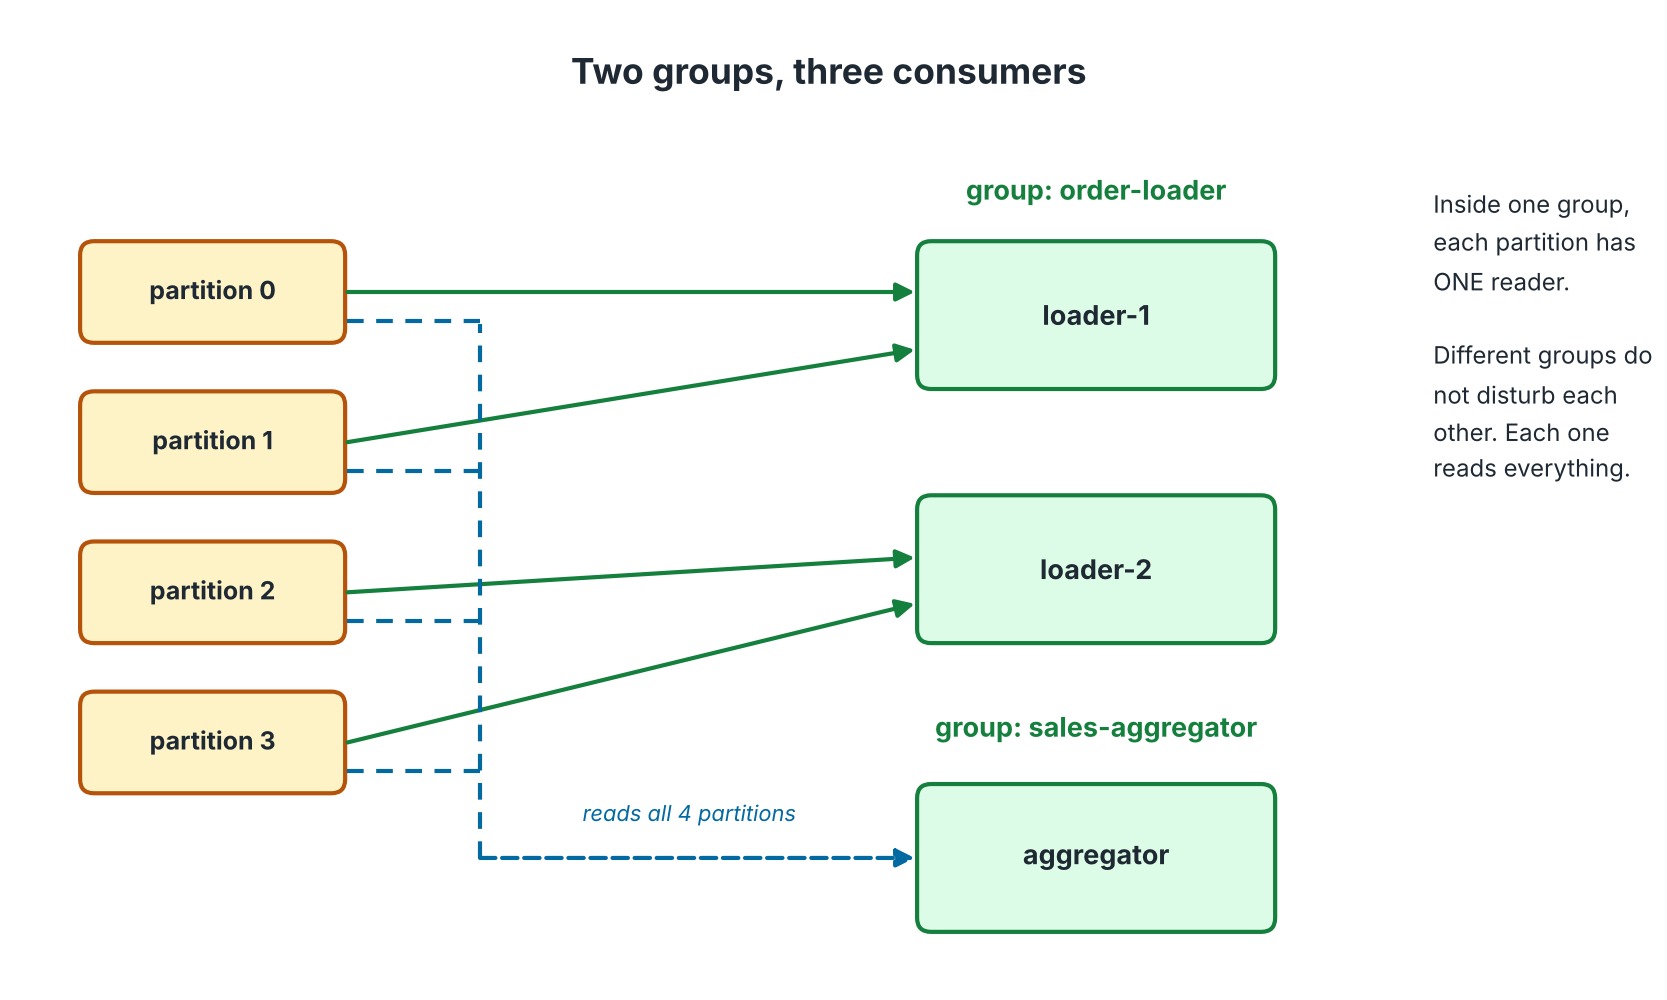 Two groups, three consumers
Two rules explain this picture:
- Inside one group, each partition is read by only one consumer. So two loaders share four partitions: two each.
- Different groups are independent. The aggregator reads all partitions, even while the loaders do the same.
Rebalancing
When a consumer joins or leaves, Kafka moves partitions between the members. This is a rebalance.
We use CooperativeStickyAssignor, exactly as you set it in the rebalancing lecture. Only the partitions that must move are moved. The others keep running. The old "stop everything" style (the default, RangeAssignor) is not used.
We add a ConsumerRebalanceListener with onPartitionsAssigned and onPartitionsRevoked, the same shape you built for RebalanceConsumer. They print "assigned" and "revoked" so you can see the rebalance happen. In onPartitionsRevoked, we also commit our progress — the same idea the rebalancing lecture raised when it talked about committing offsets for the partitions that go away.
6. The safe order of work
This is the most important idea in the whole capstone.
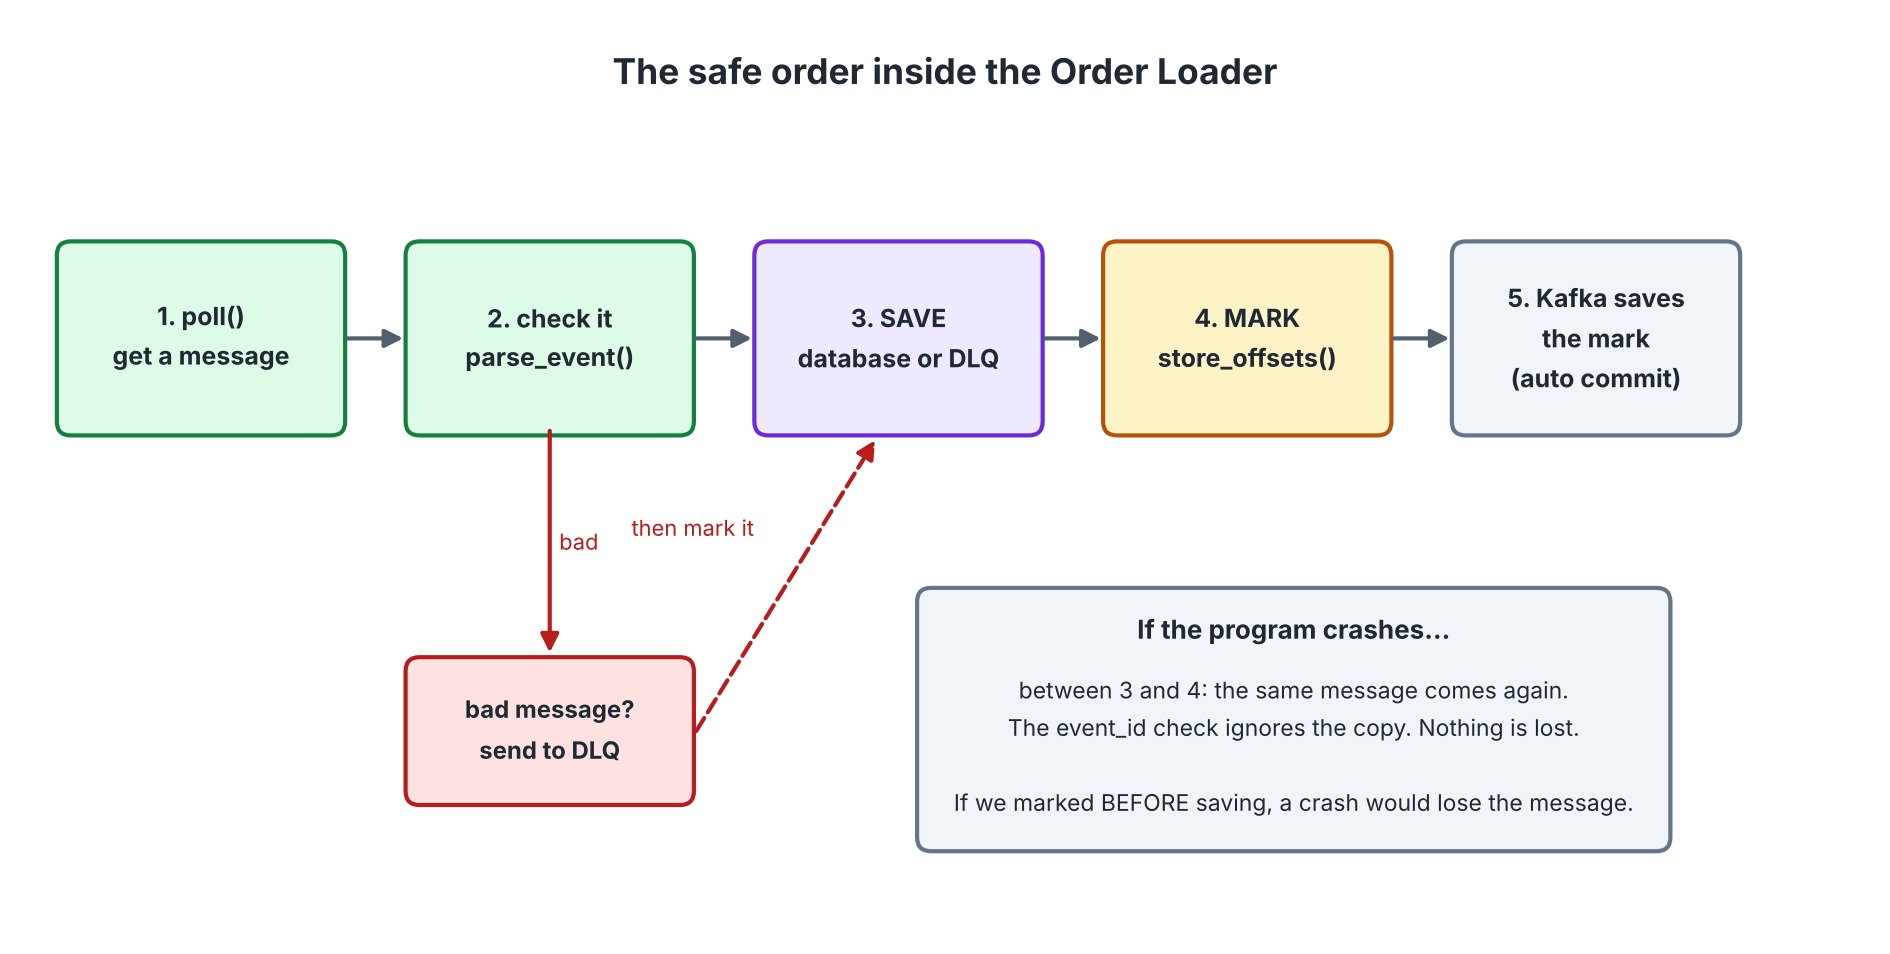 The safe order
For each message, the consumer does three things in this order:
poll()gets the message.- The program checks it, and saves the result: in the database, or in the dead-letter topic.
- Only once every record in that batch is handled, the program calls
commitSync().
This is precisely the pattern you already built for SafeConsumerWithDlq in the consumer chapter — enable.auto.commit=false, and a commit placed deliberately after the loop that processes the batch, never inside it. ShopStream does not introduce a new idea here; it applies the one you already have to a database write instead of a println.
Why save first, commit after?
Think of two ways to crash.
| Order | Crash happens | Result |
|---|---|---|
| Commit first, save second | after the commit, before the save | The message is lost. Kafka thinks it is done. |
| Save first, commit second | after the save, before the commit | The message comes again. We have already saved it. |
A message coming twice is a problem we can solve. A lost message is not. So we always save first.
How we handle the same message twice
Every event has an event_id. We keep a table of the event IDs we have processed. For each event, the database does two things in one JDBC transaction:
- Try to insert the
event_id. If it is already there, stop. This event is a duplicate. - Otherwise, save the order or the sale.
Connection.setAutoCommit(false), then a commit() at the end or a rollback() on failure — the JDBC equivalent of Python's with conn: block. Either both statements happen, or neither does, so a crash between them cannot leave half a result.
7. The orders database
One row for each order
The orders table has one row for each order_id. Each event updates that row.
Status must never go backwards
Events do not always arrive in order. Two producers send events for the same order. A DELIVERED event might arrive before SHIPPED.
This is where the Java version makes a different, more Java-native choice than a dict of numbers: OrderStatus is an enum, in the order a real order moves through, and its ordinal() is the rank:
| Status | ordinal() |
|---|---|
CREATED | 0 |
PAID | 1 |
SHIPPED | 2 |
DELIVERED | 3 |
CANCELLED | 4 |
The rule is: an event can change the status only if its rank is bigger than the current one. A late SHIPPED (2) cannot change DELIVERED (3). EventType carries its matching OrderStatus directly (ORDER_SHIPPED.status() is OrderStatus.SHIPPED), so there is exactly one place where "which event means which status" is decided, and the rank comparison is a plain integer comparison, not a lookup into a second table.
A status can arrive before the order
A SHIPPED event may arrive before ORDER_CREATED. We still save it, as a row with a status and no amount. When ORDER_CREATED comes, it fills in the customer and the amount, and does not touch a status that is further ahead.
The SQL is identical to what you would write in any SQL dialect sitting on top of SQLite: INSERT ... ON CONFLICT(order_id) DO UPDATE, with COALESCE(excluded.column, orders.column) to keep an old value when the new one is empty, and CASE WHEN excluded.status_rank > orders.status_rank to make the status move only forward. SQLite does not care which language sent the statement — this part of the design has nothing Java- or Python-specific about it at all.
8. The dead-letter topic
When the loader finds a bad message, it:
- Copies the original key and value to
shop.orders.dlq. Nothing is changed. Because the consumer readsbyte[]key and value — the sameByteArrayDeserializeryou used forSafeConsumerWithDlq— the bytes it copies are exactly the bytes it received, with no re-encoding step that could change them. - Adds three headers, built with
RecordHeader, the same header mechanism from the offset-management lecture:
| Header | Example | Why |
|---|---|---|
error | BAD_AMOUNT | A short reason code. Easy to count and search |
source | shop.orders[1]@79 | Topic, partition and offset. Find the original message |
failed_at | 2026-11-06T14:05:31.123Z | When it failed |
- Waits until Kafka confirms the copy, with
producer.send(record).get(10, TimeUnit.SECONDS). Only then does it commit the offset.
Why wait? If the copy failed and we committed anyway, the bad message would vanish with no record. The safe order applies here too.
Reason codes: keep them short and stable, in capital letters, like INVALID_JSON, MISSING_ZONE, UNKNOWN_ZONE, BAD_AMOUNT.
9. The Sales Aggregator
What it counts
Only ORDER_CREATED events. For each zone and each minute, it keeps the number of orders and the total amount.
Which clock?
There are two clocks:
- Processing time: when the consumer reads the message.
- Event time: when the message was written to Kafka.
We use the timestamp Kafka itself stored on the record — ConsumerRecord.timestamp(). Then the minute of a sale does not depend on when the consumer happens to run. If the aggregator is down for ten minutes and then catches up, the sales still fall into the right minutes.
Same safe order
It uses the same pattern as the loader: save to sales.db (with an event-ID check), then commitSync().
Bad messages
The aggregator ignores them. The loader owns the dead-letter topic. If both sent the same bad message to it, you would have each one twice.
10. The replay tool
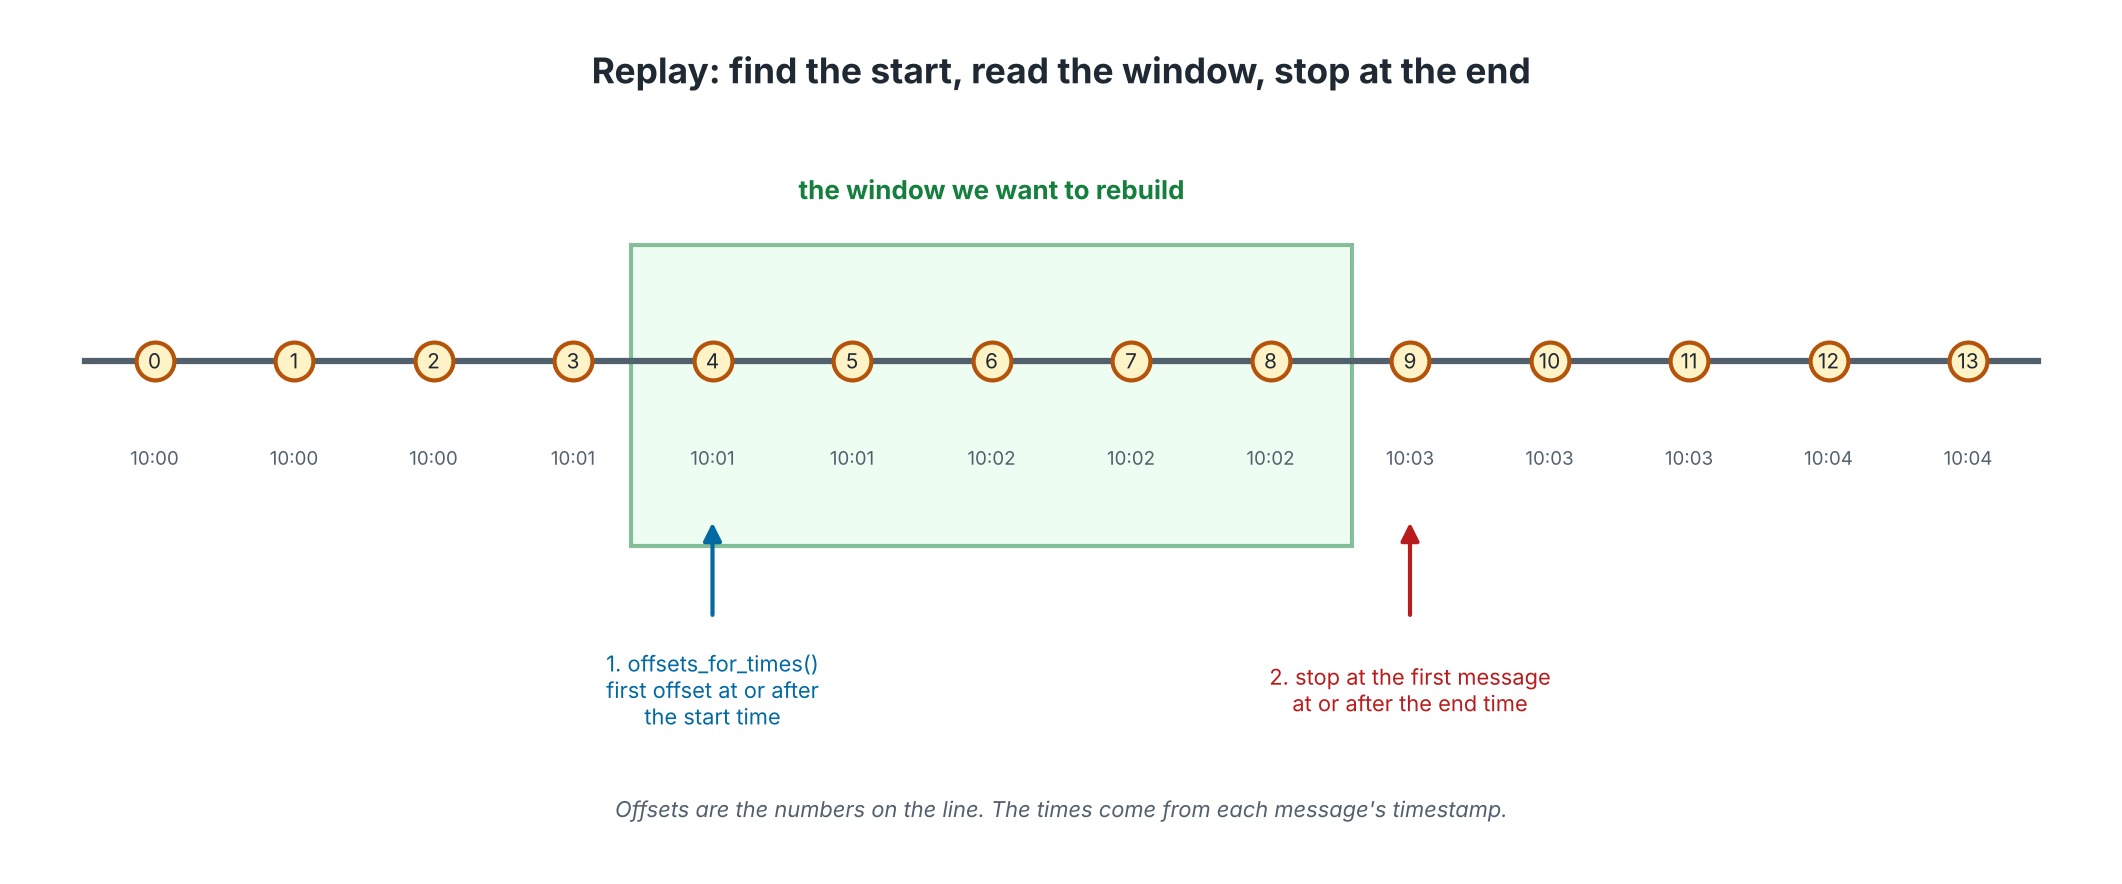 Replay window
Suppose Anita says, "The numbers between 2:05 and 2:08 look wrong. Can you rebuild them?"
If you built ReplayByTimestamp in the consumer chapter, you already have almost everything this tool needs. That tool rewound to a timestamp and read until "now." This one needs to stop at a second timestamp instead of "now," so it combines two stopping rules:
- Ask Kafka, for each partition: "What is the first offset at or after
--from?" This isoffsetsForTimes(), exactly as before. - Start reading each partition from that offset, with
assign()andseek(), notsubscribe(). - Stop reading a partition the moment a record's own timestamp reaches
--to— a new rule — or the moment the partition reaches the end offset that existed when the tool started (the chapter's original rule, still needed as a safety net for a window whose end is still in the future). - Compare the counts with
sales.db. PrintMATCHorDIFFERENT.
Important details
- No
group.idat all. Unlike thelibrdkafka-based clients, where a throw-away random group name is the usual way to stay harmless, the Java consumer lets you skipgroup.identirely when you only ever callassign(). A consumer with no group cannot join one and cannot commit — it is not merely configured to avoid disturbing production, it is incapable of it. That is a stronger version of requirement D3 than "use a name nobody else uses." - How to know a partition has ended? The Java consumer has no built-in "end of partition" signal to turn on. Reuse the trick from
ReplayByTimestamp: askendOffsets()once, before you start reading, and compareconsumer.position(partition)against it after every poll. - A partition with nothing after the start time gets back
nullfromoffsetsForTimes(). Skip it. - Time zone: all times are UTC.
11. What can go wrong, and what saves you
| Problem | What happens | What protects you |
|---|---|---|
| A producer retries a send | Could create a duplicate | Idempotent producer |
| A broker stops | A partition leader changes | Replication 3, acks=all, retries |
| The producer's buffer is full | send() blocks, then may time out | max.block.ms, a caught TimeoutException |
| A consumer crashes after saving | The message comes again | Save first, commit after, and the event_id check |
| A consumer joins or leaves | Partitions move | Cooperative rebalancing and the revoke callback |
| A message is broken | Could stop the loader | Dead-letter topic |
| Events arrive out of order | Status could go backwards | OrderStatus ranks |
SHIPPED arrives before CREATED | A missing row | Save a partial row, fill it later |
| The numbers look wrong | You need to recheck | Replay tool |
12. A good order to build things
Build in small steps. After each step, run something and see it work.
| Step | Build | Check that |
|---|---|---|
| 1 | Config and the topics | SetupTopics runs and the topics exist |
| 2 | EventType, OrderStatus, OrderEvent, InvalidEventException, EventValidator | A few good and bad examples give the right reason codes |
| 3 | Zone and ZonePartitioner | Each zone gives its own partition |
| 4 | OrderFeed | One service sends to Kafka and prints partition counts |
| 5 | OrderProducer and FulfilmentProducer | Both send their files. Counts add up to the lines in the file |
| 6 | OrderRepository and SalesRepository | Saving the same event twice changes nothing |
| 7 | OrderLoader | Good events land in orders.db. Bad ones land in the DLQ |
| 8 | SalesAggregator | sales.db fills up |
| 9 | Run it all and use VerifyResults | Every check passes |
| 10 | The failure tests | Still correct after a stop, a crash, a broker down |
| 11 | ReplaySales | MATCH for your time window |
Part 3 follows exactly these steps.
Before you open Part 3
Try the steps yourself first. Even if you only finish steps 1 to 4, you will understand Part 3 much better.
When you are stuck for more than 20 minutes on one step, open Part 3 and read only that step. Then close it and try again.